
rrreddykonda/Python3-FAQs-Chatbot
1
1�
2�~lf
-� �N�dZ ddlZddlmZe��dejd<ejd��ejd<ejd��ejd< ddlZddlmZd Z ej3d4�
��Z
ee d
e
i�
��Z
e
�
��Zeedj��edj ddlmZeddd���Ze�e��Zeee����eeedj����edj ddlmZddlmZed���Z
ej
ee
���Z
e
� dddi�
��Z e �!d
��Z"ee"��ee"dj�� dd
l#m$Z$d Z%e$e%d d!dd"ejd�#��Z&dd$l'm(Z(dd%l)m*Z*dd&l+m,Z,dd'l-m.Z.e(��Z/d(Z0e*j1e0��Z2d)�Z3e e3ze,��d*�e2ze&ze/zZ4e4�!d
��dS)+u�Build a Retrieval Augmented Generation (RAG) App.ipynb5 6Automatically generated by Colab.7 8Original file is located at9 https://colab.research.google.com/drive/1S2hX-KUWMKmFWGK-Ae9qyYCtcwseOgH-10 11## Building a Retrieval Augmented Generation (RAG) App12 13### Introduction to RAG14**Retrieval Augmented Generation (RAG)** is a powerful technique for building sophisticated question-answering (Q&A) applications using Large Language Models (LLMs). These applications can answer questions about specific source information by augmenting the knowledge of LLMs with additional, relevant data.15 16### Purpose of RAG17- **Enhancing LLMs**: LLMs are trained on public data up to a specific cutoff date. RAG enables the integration of private or more recent data, improving the model's ability to reason about this new information.18- **Application**: Used to create Q&A chatbots that can handle queries about specific data sources.19 20### Components of a RAG Application211. **Indexing**22 - **Loading Data**: Ingesting data from a source using DocumentLoaders.23 - **Splitting Text**: Breaking large documents into smaller chunks using text splitters. This makes the data easier to index and fit within the model's context window.24 - **Storing Data**: Indexing and storing the text chunks using a VectorStore and an Embeddings model.25 262. **Retrieval and Generation**27 - **Retrieving Data**: Using a Retriever to fetch relevant data chunks based on the user’s query.28 - **Generating Answers**: Using a ChatModel or LLM to produce an answer by combining the user’s question with the retrieved data.29 30### Workflow of a RAG Application311. **Indexing Phase**32 - **Load**: Import data using DocumentLoaders.33 - **Split**: Use text splitters to divide large documents into manageable chunks.34 - **Store**: Index and store these chunks in a VectorStore for efficient retrieval.35 - **Diagram**: Visual representation of the indexing process shows data loading, splitting, and storing in an indexed format.36 37 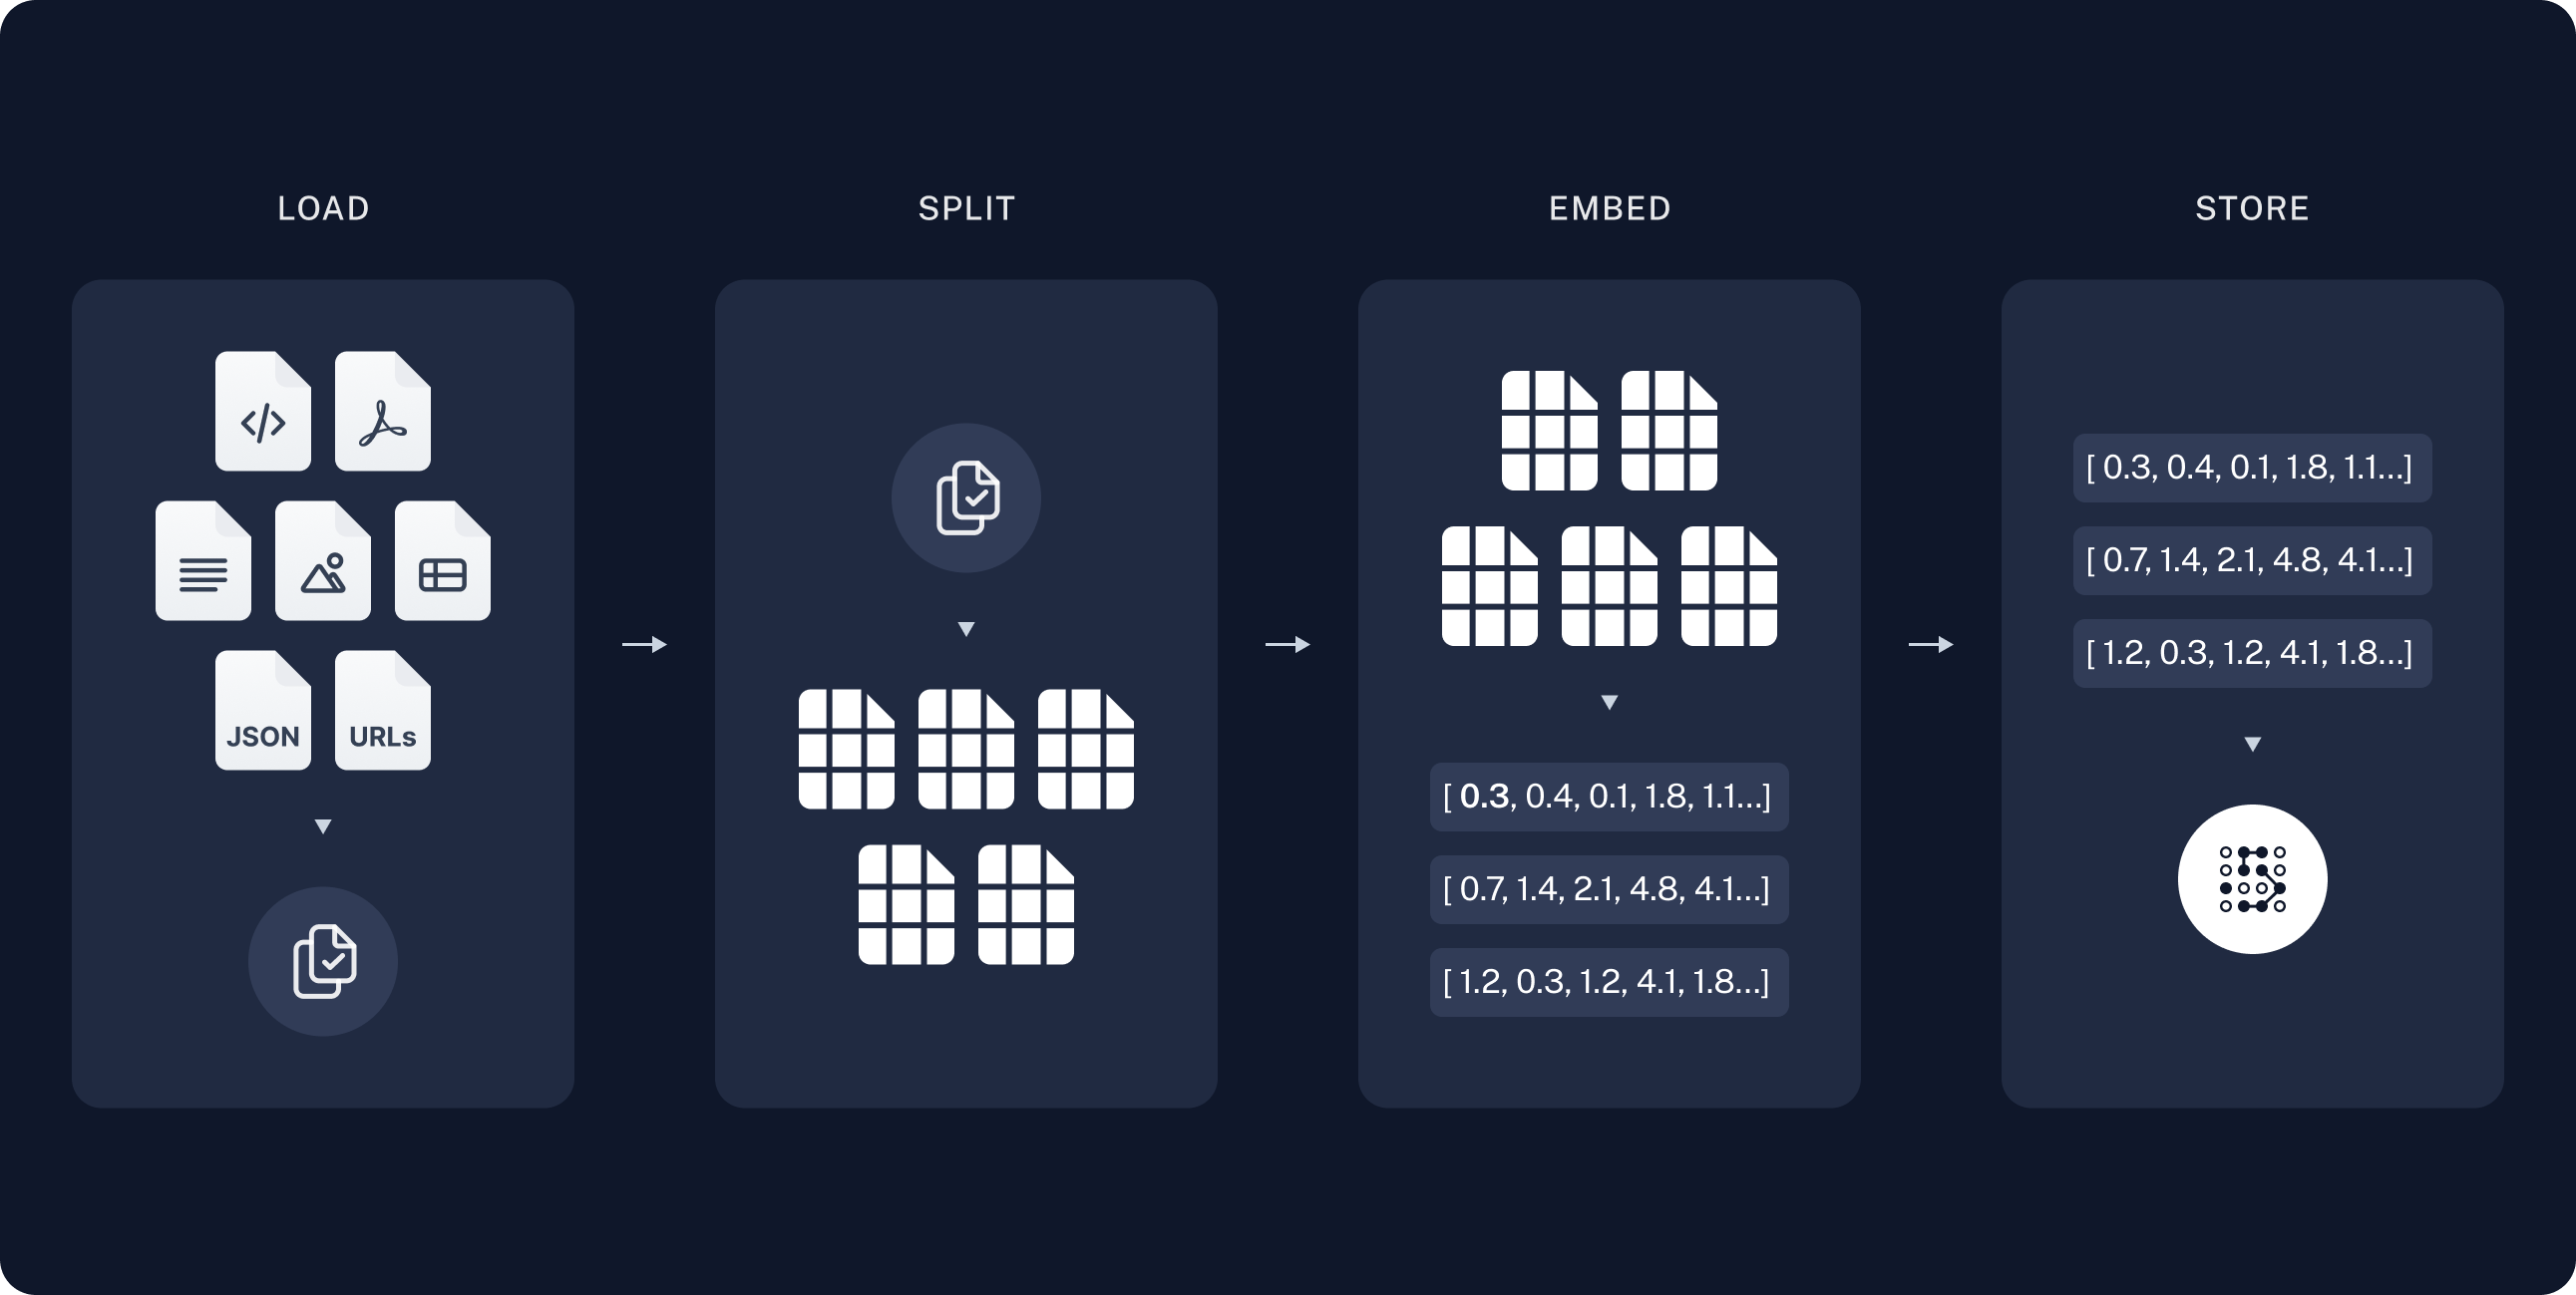38 392. **Retrieval and Generation Phase**40 - **Retrieve**: Upon receiving a user query, the system retrieves the most relevant chunks of data from the VectorStore.41 - **Generate**: The retrieved data, combined with the user’s query, is used by the LLM to generate a coherent and relevant answer.42 43 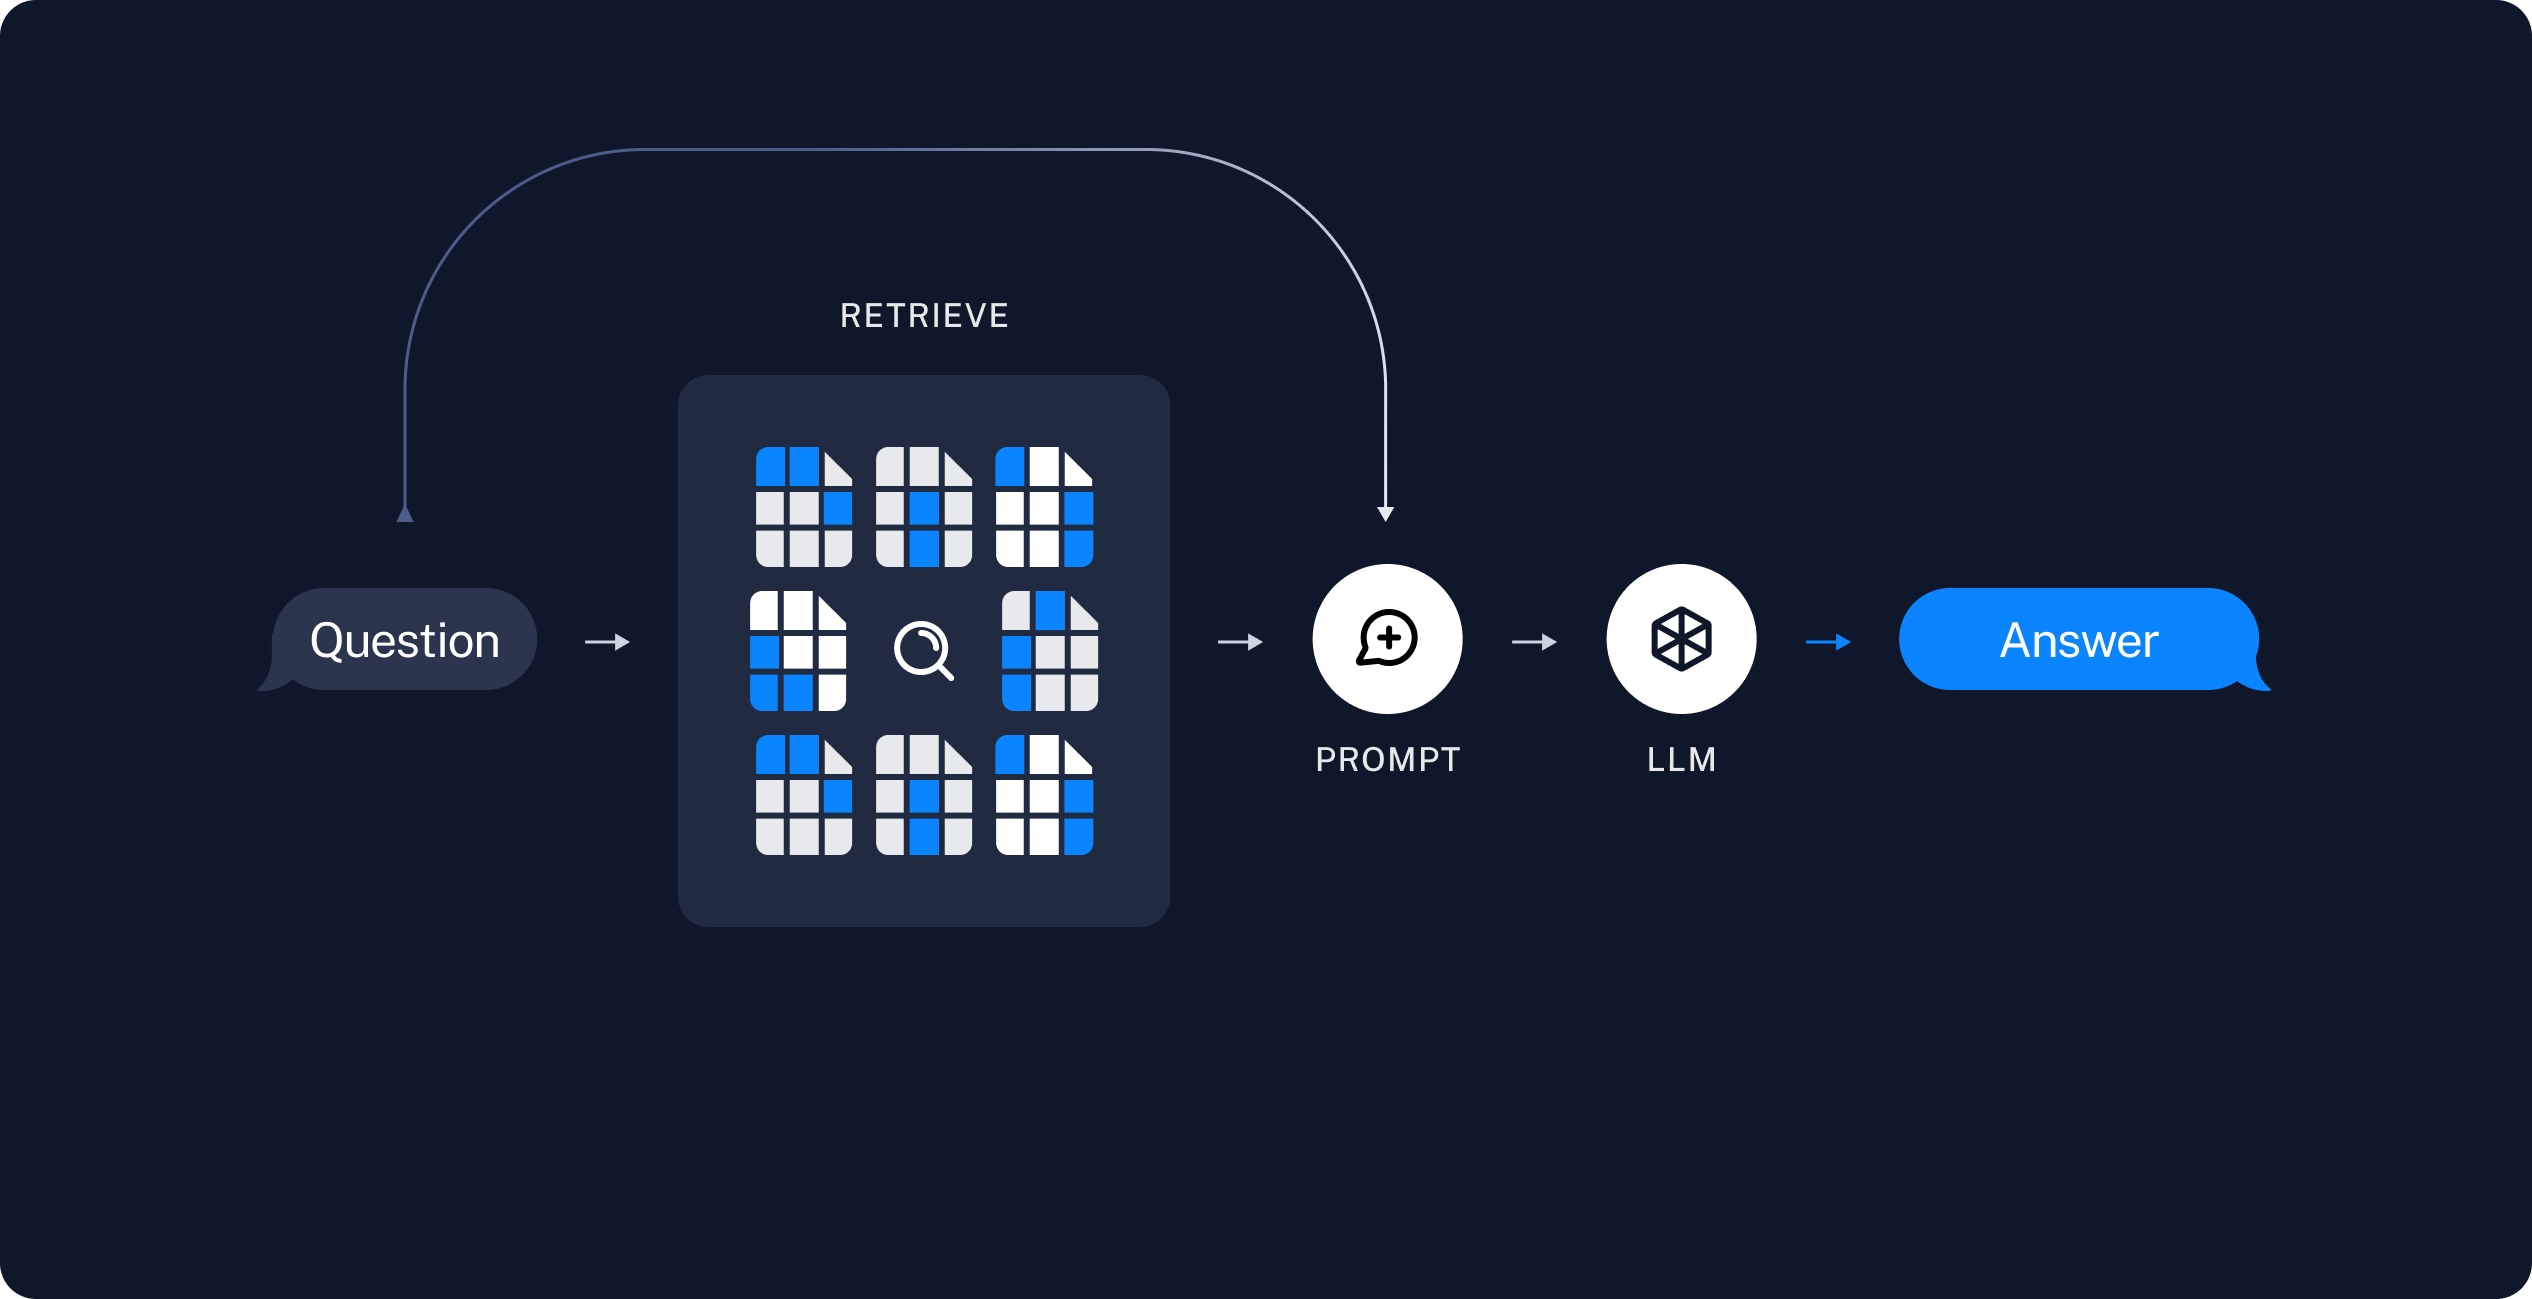44 45### Tools and Technologies46- **LangChain**: Provides components to build Q&A applications and RAG systems.47- **DocumentLoaders**: For loading data into the system.48- **Text Splitters**: For breaking down documents into smaller chunks.49- **VectorStore**: For storing and indexing data chunks.50- **Embeddings Model**: To transform data chunks into searchable vector representations.51- **Retriever**: To fetch relevant data chunks based on user queries.52- **ChatModel/LLM**: To generate answers using the retrieved data and user query.53 54### Example Application Workflow551. **Data Ingestion**: Load a large text document using DocumentLoaders.562. **Data Preparation**: Split the document into smaller, manageable chunks with text splitters.573. **Data Indexing**: Store these chunks in a VectorStore, indexed using an Embeddings model.584. **Query Processing**:59 - When a user submits a query, the Retriever searches the VectorStore for relevant data chunks.60 - The retrieved data is combined with the user’s query and fed into a ChatModel or LLM.61 - The model generates and returns a relevant answer to the user.62 63### Advanced Techniques and Resources64- **LangSmith**: A tool to trace and understand the application, becoming more valuable as the application's complexity increases.65- **RAG over Structured Data**: For those interested in applying RAG to structured data like SQL databases, that can also possible using LangChain.66 67 68 69let's dive into hands-on coding!70 71## Installation & setup72�N)�
load_dotenv�true�LANGCHAIN_TRACING_V2�LANGCHAIN_API_KEY�HUGGINGFACEHUB_API_TOKEN)�
WebBaseLoader)z*https://docs.python.org/3/faq/general.htmlz.https://docs.python.org/3/faq/programming.htmlz)https://docs.python.org/3/faq/design.htmlz*https://docs.python.org/3/faq/library.htmlz,https://docs.python.org/3/faq/extending.htmlz*https://docs.python.org/3/faq/windows.htmlz&https://docs.python.org/3/faq/gui.htmlz,https://docs.python.org/3/faq/installed.html�body)�class_�73parse_only)�web_path� bs_kwargs)�
RecursiveCharacterTextSplitteri���T)�74chunk_size�
chunk_overlap�add_start_index��)�HuggingFaceHubEmbeddings)�Chromaz'sentence-transformers/all-mpnet-base-v2)�repo_id)� documents� embedding�75similarity�k�)�
search_type�
search_kwargsz%How do I freeze Tkinter applications?)�HuggingFaceEndpointz"mistralai/Mistral-7B-Instruct-v0.3ztext-generationg333333�?F)r�task�
temperature�max_new_tokens�return_full_text�huggingfacehub_api_token)�StrOutputParser)�PromptTemplate)�RunnablePassthrough)�
StreamingStdOutCallbackHandlera�Use the following pieces of context to answer the question at the end.76Only answer the question from the context don't generate any additional infrormation.77If you don't get enough information from the context, just say that "I don't have information about this question". I can only answer questions from the source url https://docs.python.org/3/faq/index.html.78Always say "thanks for asking!" at the end of the answer.79 80{context}81 82Question: {question}83 84Helpful Answer:c�@�d�d�|D����S)Nz85 86c3�$K�|]
}|jV��
dS)N)�
page_content)�.0�docs �`/Users/rb/Documents/Raghu/Projects/GenAI/langchain/PythonFAQsChatBot/Python3-FAQs-Chatbot/Rag.py� <genexpr>z'extract_page_content.<locals>.<genexpr>�s%����8�8�C�s�'�8�8�8�8�8�8�)�join)�docss r-�extract_page_contentr2�s#��
�;�;�8�8�4�8�8�8�
8�
8�8r/)�context�question)5�__doc__�os�dotenvr�environ�getenv�bs4�$langchain_community.document_loadersr� web_paths�
SoupStrainer�
bs4_strainer�loader�loadr1�lenr*�langchain.text_splitterr�
text_splitter�split_documents�87all_splits�print�metadata�langchain.embeddingsr�langchain.vectorstoresr�88embeddings�from_documents�
vectorstore�
as_retriever� retriever�invoke�retrieved_docs�langchain.llmsr
r�llm�
langchain_core.output_parsersr$�langchain.promptsr%�langchain.schema.runnabler&�$langchain.callbacks.streaming_stdoutr'�parser�template�
from_template�custom_rag_promptr2� rag_chain�r/r-�<module>r]s���D�D�P�89� � � �
�
�
�
�
�
�
�
�
�
�
�%+��90�
!�"�"+�"�)�,?�"@�"@��91�
� �)2���3M�)N�)N��92�
%�&��
�93�94�95�>�>�>�>�>�>�
=� � �s� ��0�0�0�
� �
� �".�
�!=�96�97�98���{�{�}�}����D��G������Q�����C�B�B�B�B�B�.�.�$�c�cg�h�h�h�
�
�
*�
*�4�
0�
0�99���c�c�*�o�o������c�c�*�Q�-�100$�%�%�&�&�&�101�3�����:�9�9�9�9�9�)�)�)�)�)�)�
%�
%�.W�
X�
X�
X�102�#�f�#�j�J�O�O�O�
��
�
$�
$�
�c�ST�X�
$�
V�
V� ��!�!�"I�J�J����N������n�Q��$�%�%�%��/�.�.�.�.�.�103.����'� 0�&)�#�+0�35�:�>X�3Y�
�
�
��:�9�9�9�9�9�,�,�,�,�,�,�9�9�9�9�9�9�O�O�O�O�O�O� � � � ��
��2�^�1�(�;�;��9�9�9��
0�0�>Q�>Q�>S�>S�T�T��� �104�
�
�105�
106���8�9�9�9��r/