
facebook/data2vec-text-base
126.2k
1---2language: en3tags:4- exbert5license: mit6datasets:7- bookcorpus8- wikipedia9---10 11# Data2Vec-Text base model12 13Pretrained model on English language using the *data2vec* objective. It was introduced in14[this paper](https://arxiv.org/abs/2202.03555) and first released in15[this repository](https://github.com/pytorch/fairseq/tree/main/examples/data2vec). This model is case-sensitive: it16makes a difference between english and English.17 18Disclaimer: The team releasing Data2Vec-Text did not write a model card for this model so this model card has been written by19the Hugging Face team.20 21## Pre-Training method22 23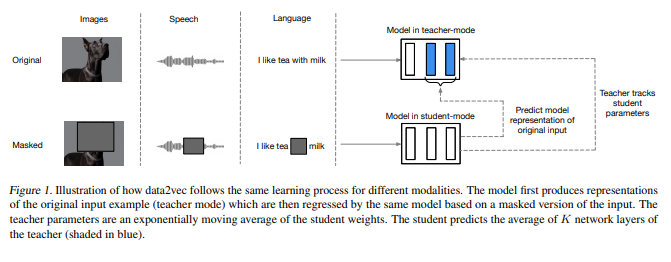24 25For more information, please take a look at the [official paper](https://arxiv.org/abs/2202.03555).26 27## Abstract28 29*While the general idea of self-supervised learning is identical across modalities, the actual algorithms and objectives differ widely because30they were developed with a single modality in31mind. To get us closer to general self-supervised32learning, we present data2vec, a framework that33uses the same learning method for either speech,34NLP or computer vision. The core idea is to predict latent representations of the full input data35based on a masked view of the input in a selfdistillation setup using a standard Transformer architecture. Instead of predicting modality-specific36targets such as words, visual tokens or units of37human speech which are local in nature, data2vec38predicts contextualized latent representations that39contain information from the entire input. Experiments on the major benchmarks of speech40recognition, image classification, and natural language understanding demonstrate a new state of41the art or competitive performance to predominant approaches.*42 43## Intended uses & limitations44 45The model is intended to be fine-tuned on a downstream task.46See the [model hub](https://huggingface.co/models?filter=data2vec-text) to look for fine-tuned versions on a task that47interests you.48 49Note that this model is primarily aimed at being fine-tuned on tasks that use the whole sentence (potentially masked)50to make decisions, such as sequence classification, token classification or question answering. For tasks such as text51generation you should look at model like GPT2.52 53## Training data54 55The RoBERTa model was pretrained on the reunion of five datasets:56- [BookCorpus](https://yknzhu.wixsite.com/mbweb), a dataset consisting of 11,038 unpublished books;57- [English Wikipedia](https://en.wikipedia.org/wiki/English_Wikipedia) (excluding lists, tables and headers) ;58- [CC-News](https://commoncrawl.org/2016/10/news-dataset-available/), a dataset containing 63 millions English news59 articles crawled between September 2016 and February 2019.60- [OpenWebText](https://github.com/jcpeterson/openwebtext), an opensource recreation of the WebText dataset used to61 train GPT-2,62- [Stories](https://arxiv.org/abs/1806.02847) a dataset containing a subset of CommonCrawl data filtered to match the63 story-like style of Winograd schemas.64 65Together theses datasets weight 160GB of text.66 67### BibTeX entry and citation info68 69```bibtex70@misc{https://doi.org/10.48550/arxiv.2202.03555,71 doi = {10.48550/ARXIV.2202.03555},72 url = {https://arxiv.org/abs/2202.03555},73 author = {Baevski, Alexei and Hsu, Wei-Ning and Xu, Qiantong and Babu, Arun and Gu, Jiatao and Auli, Michael},74 keywords = {Machine Learning (cs.LG), FOS: Computer and information sciences, FOS: Computer and information sciences},75 title = {data2vec: A General Framework for Self-supervised Learning in Speech, Vision and Language},76 publisher = {arXiv},77 year = {2022},78 copyright = {arXiv.org perpetual, non-exclusive license}79}80```