
ZeyuLing/HFTrainer-StyleGAN2-ADA-FFHQ-1024
Install the HFTrainer repository before running the commands below. This repository hosts the processed pretrained base; the public-data training outputs are separate. Artifact provenance.
StyleGAN2-ADA · FFHQ 1024
Unconditional image generation with repository-owned model, trainer and inference code.
Verified: 20 real-data training steps, saved checkpoint and native checkpoint-only base inference. Convergence is not established.
All models · Settings · Train · Infer · Evidence · Demos
At a glance
Sources
Original paper / report · Original code · ADA paper
The original repository is provenance, not a runtime checkout requirement. Third-party notices preserve implementation and asset terms.
Settings and checkpoints
Only the setting above is a released HFTrainer artifact. Its root config.json, weights and all task-required component configs, processors and schedulers are included together. Inference needs only the checkpoint path or Hub ID, plus task inputs.
Pinned weight revision: `dc9ff4e65f66`. Original conversion evidence describes the initial export; the current revision adds checkpoint-only dispatch metadata without changing tensors.
Setup
Run from the repository root:
python -m pip install -e "."
python -m pip install "huggingface_hub>=0.34,<2"
Verified on one NVIDIA H200 with PyTorch 2.8.0+cu128. This is the tested environment, not a measured minimum-memory requirement.
Data
The recipe downloads `ZeyuLing/hftrainer_smithsonian_butterflies` to data/hftrainer_smithsonian_butterflies. Split counts: 900 train / 100 validation / 0 test. Dataset source, license, transformations and checksum verification are documented in Public demo datasets.
Model features are cached locally when required. The script never substitutes synthetic samples for missing real media.
Train
One command downloads pinned data and weights, prepares required caches, and runs the 20-step recipe:
python tools/run_public_demo.py stylegan2Reuse downloaded weights with --checkpoint path/to/complete_bundle; change the output directory with --work-dir path/to/run. The underlying command is python tools/train.py configs/public_data/stylegan2.py. Seed: 42. Training logs and checkpoints are saved under work_dirs/public_data/stylegan2/. If you reused a custom checkpoint directory, set HFTRAINER_CHECKPOINT to that directory before directly invoking training, resume or export commands.
The final resumable checkpoint is work_dirs/public_data/stylegan2/checkpoint-iter_20. For a longer resumed run, keep the same checkpoint/data setting:
python tools/train.py configs/public_data/stylegan2.py --auto-resume \
  --cfg-options train_cfg.max_iters=40
Infer
Run the processed pretrained base, independently of any training config:
python tools/infer.py --model ZeyuLing/HFTrainer-StyleGAN2-ADA-FFHQ-1024 \
  --revision dc9ff4e65f66f18491e75a147c2895871e582e36 --device cuda --seed 42 \
  --output outputs/stylegan2.png
--model also accepts a local complete checkpoint directory. A resumable training checkpoint is not a standalone model: export with tools/export_model.py using the matching training config, then pass the exported directory to --model. Artifact and configuration contract.
To package this training run as a complete checkpoint (including its frozen base components):
python tools/export_model.py --config configs/public_data/stylegan2.py \
  --checkpoint work_dirs/public_data/stylegan2/checkpoint-iter_20 --output exports/stylegan2
Then run the inference command above with --model exports/stylegan2 and omit --revision. Complete exports duplicate the base weights; allow sufficient disk space.
Evidence and loss
The local generator matches official NVIDIA FP32 1024-pixel output exactly with constant noise and seed 42, and remains identical after reload.
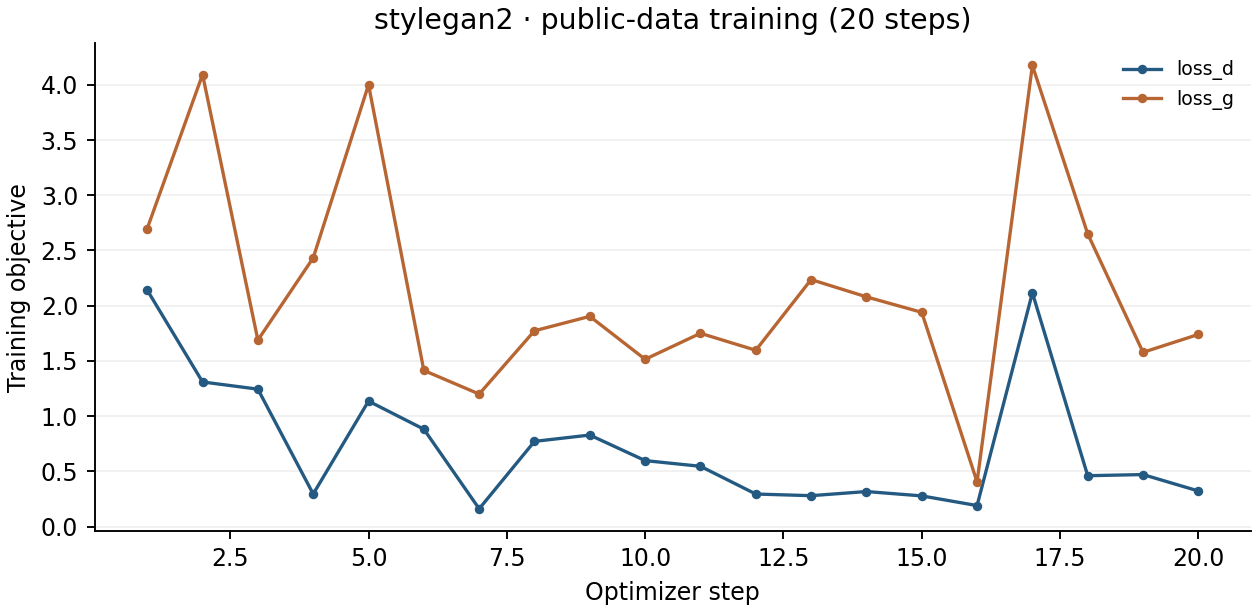
Raw training record · Training log
These are raw, unsmoothed objectives on the public dataset. Twenty steps establish pipeline execution, not convergence. Loss values are not comparable across models.
No held-out perceptual quality metric was measured for this short run.
Demos
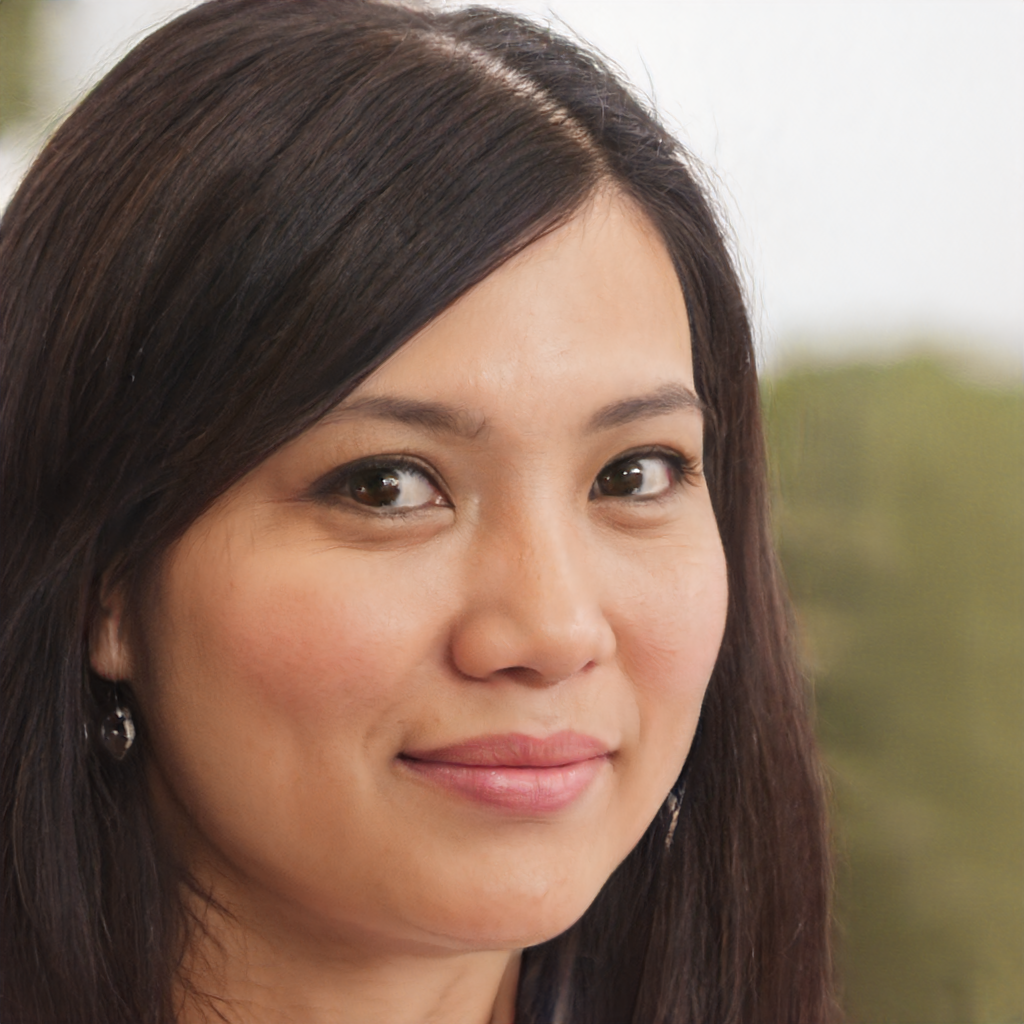
Untouched published base; seed 42. The prompt and sampler settings are the inference command above. This image is not an output of the 20-step fine-tuned model.
Limitations
This short run transfers a face generator toward butterfly images and does not establish successful domain adaptation. The demo below remains an untouched FFHQ base sample. Training includes local R1/path-length objectives, but does not reproduce the complete ADA training recipe. No FID is claimed. NVIDIA assets retain their non-commercial license.
Citation
@misc{karras2020stylegan2,
  title = {Analyzing and Improving the Image Quality of StyleGAN},
  author = {Tero Karras and others},
  year = {2020},
  eprint = {1912.04958},
  archivePrefix = {arXiv},
  url = {https://arxiv.org/abs/1912.04958}
}
@inproceedings{karras2020ada,
  title = {Training Generative Adversarial Networks with Limited Data},
  author = {Tero Karras and others},
  booktitle = {NeurIPS},
  year = {2020},
  url = {https://arxiv.org/abs/2006.06676}
}
Also retain the dataset citation and attribution.